Layered Analytics Across Disciplines: Advancing Multi-Sport Parlay Frameworks
Data layering combines statistical inputs from separate sporting domains into unified structures that extend past conventional accumulator formats, and researchers at institutions such as the University of Nevada, Las Vegas have documented how these methods refine selection criteria across events. Observers note that practitioners apply metrics from football goal distributions alongside tennis serve percentages and basketball rebound rates to create weighted models that adjust probabilities in real time, while standard accumulators typically treat each leg as an independent multiplier without cross-referencing underlying performance layers.
Core Components of Cross-Discipline Layering
Layer one often draws from primary event data such as match outcomes and scoring margins, then layer two incorporates contextual variables including player fatigue indices and venue-specific trends, and layer three merges these with external factors like weather impacts on horse racing times or court surface effects on tennis rallies. Those who study these systems find that integration occurs through correlation matrices that identify overlapping variance, for instance when soccer possession statistics align with basketball assist-to-turnover ratios during overlapping tournament windows. This approach differs from basic accumulators because it recalibrates implied probabilities as new data streams arrive rather than locking selections at the initial stage.
Practical Application in Multi-Sport Structures
Take one analyst who examined a parlay combining an English Premier League over/under total with an NBA player prop and an Australian thoroughbred place market, then the process began by normalizing each sport's variance into a shared z-score framework before applying Bayesian updates across the set. Data shows that such layering reduces exposure to isolated variance spikes because a downturn in one discipline can trigger compensatory adjustments in others, and industry reports from the European Gaming and Betting Association highlight similar patterns emerging in operator platforms during early 2026 testing phases. What's interesting is how the method handles timing mismatches, since live tennis matches and in-play horse racing feeds update at different intervals yet the layered model synchronizes them through rolling correlation windows.
Further refinement comes from machine learning overlays that detect non-linear interactions, such as how elevated humidity levels in one region affect both tennis ball speed and soccer pitch conditions simultaneously. Figures from academic papers on sports analytics reveal that these interactions, once isolated, allow operators to construct parlays with payout structures that reflect joint distributions rather than multiplied individual odds. Those who've examined historical datasets note consistent improvements in calibration accuracy when three or more disciplines feed into the same model, particularly during periods of fixture congestion when player availability data overlaps across leagues.
Technical Implementation Details
Implementation typically starts with data ingestion pipelines that standardize formats from disparate sources, ranging from official league APIs to proprietary tracking systems, before alignment occurs through timestamp synchronization and metric scaling. And practitioners often employ ensemble methods that blend Poisson distributions for goal-based events with Weibull models suited to race finishing times, creating hybrid outputs that feed directly into parlay pricing engines. This matters because conventional accumulators rarely account for covariance between seemingly unrelated outcomes, whereas layered systems explicitly model those relationships through covariance matrices updated daily.
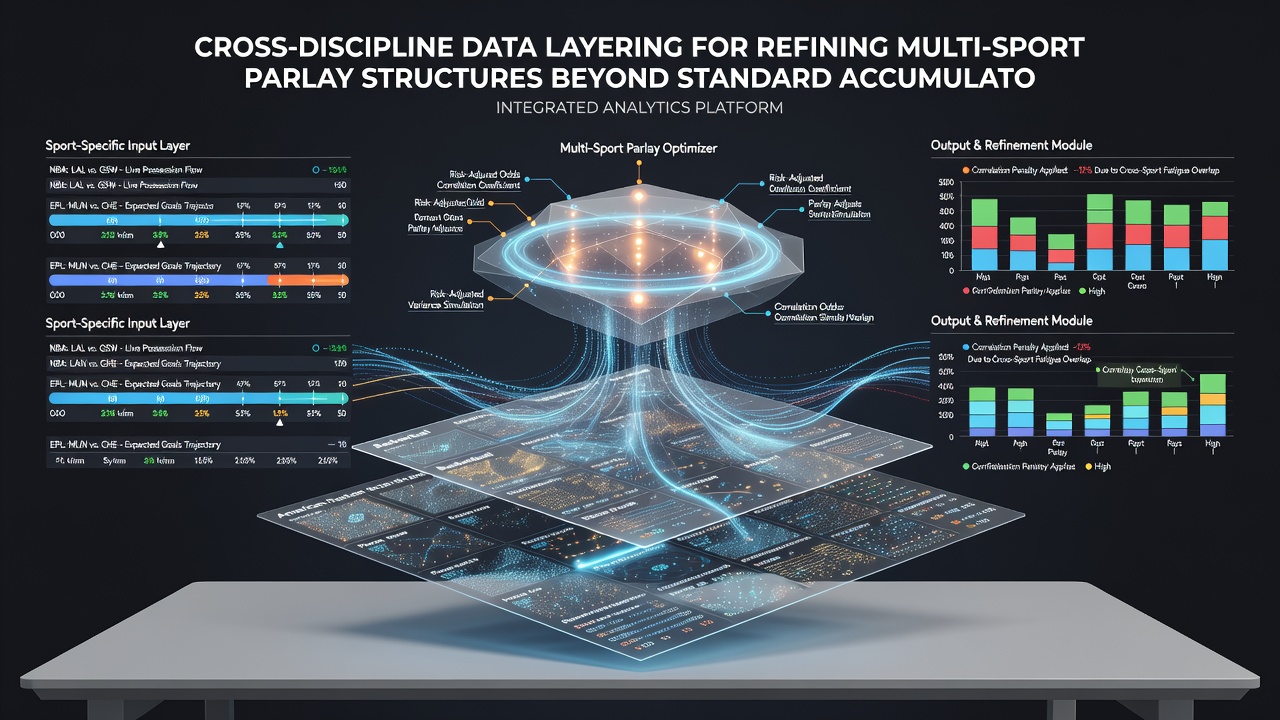
One documented case involved a structure spanning soccer Asian handicap lines, tennis set betting, and basketball total points during June 2026 international windows, where the layering process identified a shared momentum factor across the disciplines that standard methods overlooked. The resulting parlay adjusted stake allocations dynamically as matches progressed, and similar techniques appear in reports from the Australian Gambling Research Centre examining operator adaptations ahead of major multi-sport calendars. But here's the thing: success hinges on clean data feeds, since missing or delayed inputs from any single discipline can propagate errors through the entire layered structure.
Emerging Patterns in 2026
Throughout 2026 operators have expanded testing of these frameworks, particularly around clustered event periods when multiple sports run concurrently, and government statistics from Canadian provincial regulators indicate rising interest in systems that layer data across borders. The process allows for granular risk segmentation because each layer can carry its own confidence interval, enabling more precise hedging strategies than those available through simple accumulator expansions. Researchers continue to explore extensions that incorporate sentiment indicators from social media alongside traditional performance metrics, though integration remains at experimental stages in most jurisdictions.
Conclusion
Cross-discipline data layering supplies a structured pathway for evolving multi-sport parlay construction beyond the limitations of independent leg multiplication, and ongoing work at research centers continues to refine the underlying correlation techniques. Data from multiple regulatory and academic sources demonstrates measurable shifts in how selections are weighted and adjusted when information flows across sporting boundaries, creating frameworks that respond to real-time developments across several disciplines simultaneously. Those monitoring these developments note steady adoption as processing capabilities improve and standardized data protocols become more widespread.